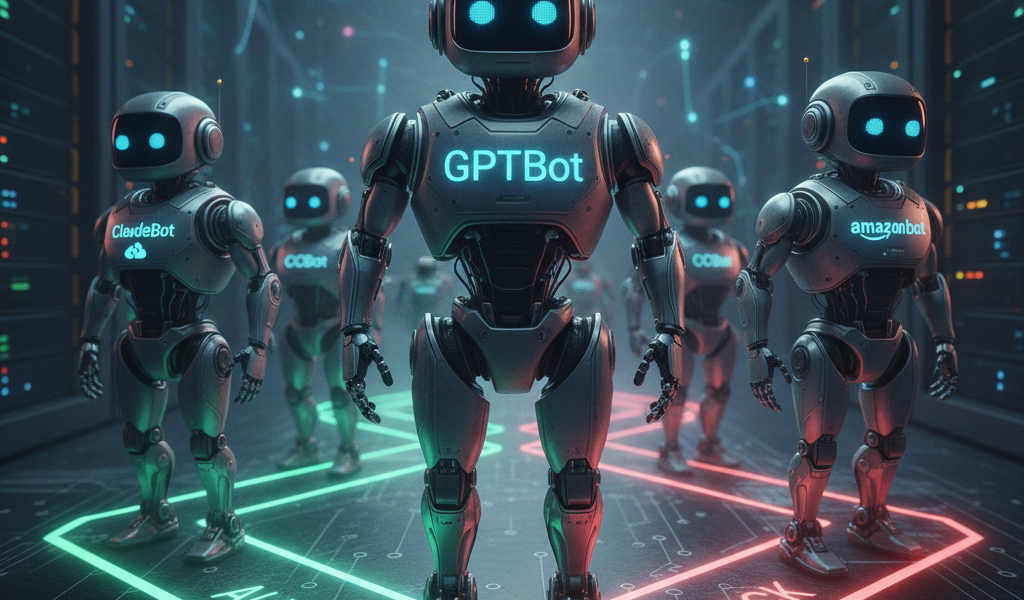
If you manage a website, you’ve probably noticed some unfamiliar names turning up in your server logs lately. ClaudeBot, GPTBot, CCBot, Amazonbot — these are just a few of the AI crawlers now systematically working their way across the web, harvesting content to train large language models. The question of whether to block or allow AI crawlers like ClaudeBot is no longer a niche technical debate. It’s a real decision that affects content creators, businesses, and site owners of every size.
This article breaks down what these bots actually do, who’s behind them, and how to make a genuinely informed choice about your own website.
What Is ClaudeBot — and Why Is It on Your Site?
ClaudeBot is the web crawler operated by Anthropic, the company behind the Claude family of AI assistants. Its primary purpose is to collect publicly available text from websites to train and improve Claude’s language models.
Unlike a search engine crawler, ClaudeBot isn’t indexing your site to send you traffic. It’s reading your content to help an AI learn from it. Whether you consider that useful, exploitative, or somewhere in between depends heavily on your perspective and business interests.
Anthropic follows a convention called robots.txt — the widely recognised standard that tells crawlers what they can and cannot access on your site. However, compliance with that file is voluntary, not legally enforced, which is a critical nuance many site owners miss.
The Full Cast: Other AI Crawlers You Should Know
ClaudeBot isn’t alone. There’s a growing ecosystem of AI bots making rounds across the internet, each with its own parent company and stated purpose.
The Main Players
- GPTBot — OpenAI’s crawler, used to train ChatGPT and related models
- CCBot — Operated by Common Crawl, a nonprofit that archives the web and supplies data to many AI projects
- Google-Extended — Google’s opt-out token for its AI training (Bard/Gemini), separate from its search crawler
- Amazonbot — Amazon’s crawler, linked to Alexa and potentially Amazon’s broader AI development
- Bytespider — Associated with ByteDance (TikTok’s parent company), widely flagged for aggressive crawling behaviour
- PerplexityBot — Runs for Perplexity AI, a generative search engine
What Makes Them Different from Search Bots
Search bots like Googlebot crawl your site to index it, which can result in organic traffic and visibility. AI training crawlers generally offer no direct benefit to you — no rankings, no referrals, no attribution. This asymmetry is at the heart of why many content creators are pushing back.
Why Some Site Owners Choose to Block AI Crawlers
The case for blocking is straightforward: your content has value, and handing it over for free to train commercial AI products doesn’t benefit you directly.
For publishers, bloggers, and media organisations, this is particularly acute. Outlets like The New York Times and The Atlantic have updated their terms of service specifically to prohibit AI scraping, and several have pursued or threatened legal action. If large newsrooms are drawing hard lines, smaller publishers have good reason to think carefully too.
Bandwidth and Performance Concerns
Aggressive crawlers can add measurable load to a server, especially on smaller hosting plans. Some site owners have reported significant spikes in bandwidth consumption from AI bots — in some documented cases, bots like Bytespider have crawled sites more aggressively than Googlebot itself.
Protecting Proprietary Content
If your site contains original research, premium content, proprietary databases, or creative work, you may have a strong business reason to block bots. Once your content is absorbed into a training dataset, there’s no practical way to remove it.
No Clear Reciprocal Benefit
With search engines, the implicit deal is crawl access in exchange for discovery. With AI crawlers, no such exchange exists. If your business model relies on people visiting your site to read content, an AI that summarises that content for users instead may actually reduce your traffic over time.
Why Some Site Owners Choose to Allow AI Crawlers
Blocking isn’t automatically the right answer. There are legitimate reasons to let these bots through.
For businesses that offer products or services — rather than content itself — having their information included in AI training data could actually improve visibility. When someone asks Claude or ChatGPT about a topic adjacent to your business, having your content in the training set might influence the quality and relevance of responses. That’s speculative, but it’s a reasonable consideration.
The Emerging Landscape of AI Search
Generative AI tools are increasingly being used as search alternatives. Perplexity AI, for example, directly cites sources and links back to them. Allowing PerplexityBot, specifically, could mean your content gets attributed and surfaced as a source — more like traditional SEO than you might expect.
Some forward-thinking content strategists are already thinking about "AEO" (Answer Engine Optimisation), deliberately structuring content to be useful to AI systems. If that becomes a meaningful traffic channel, blocking all AI bots now could close a door worth keeping open.
How to Block or Allow AI Crawlers: A Practical Guide
The main tool here is your robots.txt file, which lives at the root of your domain (e.g., yoursite.com/robots.txt). Every major AI crawler is supposed to check this file before crawling.
Blocking Specific Bots
To block ClaudeBot specifically, add the following to your robots.txt:
User-agent: ClaudeBot
Disallow: /
You can do the same for other bots by swapping in their user-agent strings:
User-agent: GPTBot
Disallow: /
User-agent: CCBot
Disallow: /
User-agent: Google-Extended
Disallow: /
User-agent: Bytespider
Disallow: /
User-agent: PerplexityBot
Disallow: /
Allowing Specific Bots While Blocking Others
If you want to allow, say, PerplexityBot (because it cites sources) while blocking the rest, just omit it from your disallow list or explicitly allow it:
User-agent: PerplexityBot
Allow: /
A Word on Enforcement
Robots.txt is a convention, not a legal barrier. Reputable companies like Anthropic, OpenAI, and Google have publicly committed to respecting it. However, less scrupulous operators may ignore it entirely. For stronger protection, some site owners use server-side IP blocking or commercial bot management tools like Cloudflare’s AI Scrapers blocking feature, which was introduced in 2024 as a direct response to this issue.
The Legal Dimension: Where Things Stand
Several high-profile lawsuits are working their way through courts — particularly in the United States — challenging whether AI companies can use web-scraped content without permission or compensation. In 2023, the Authors Guild filed suit against OpenAI. Getty Images pursued legal action against Stability AI. The New York Times launched proceedings against both OpenAI and Microsoft.
These cases are still unresolved, but the outcome could reshape the legal landscape significantly. Site owners in the EU should also pay attention to the EU AI Act, which is in the process of implementation and includes provisions around training data transparency and compliance obligations.
No matter where you’re based, it’s worth keeping an eye on these developments. What’s an informal best practice today could become a regulated requirement tomorrow.
Thinking About It From a Business Perspective
Here’s a simple framework for making your decision:
- Are you a content business? Your content is your product. Strong case for blocking.
- Are you a service or product business using content for marketing? More nuanced — consider allowing bots that cite sources, blocking ones that don’t.
- Do you have a small or shared hosting plan? Aggressive crawlers can genuinely impact performance. Consider blocking the most resource-intensive ones.
- Are you publishing sensitive, proprietary, or regulated information? Block broadly and consult legal advice.
There’s no universal answer. The right call depends on your business model, your content type, and your appetite for engaging with an evolving landscape.
Frequently Asked Questions
What exactly does ClaudeBot do when it visits my site?
ClaudeBot reads the publicly accessible text on your pages and collects it as potential training data for Anthropic’s Claude AI models. It doesn’t index your content for search results or send you any traffic in return. Think of it as a very thorough reader that never becomes a customer.
Is blocking AI crawlers bad for my SEO?
No — blocking ClaudeBot, GPTBot, or similar AI training bots has no effect on your search engine rankings. These are entirely separate systems from Googlebot or Bingbot. Just be careful to use the correct user-agent names so you don’t accidentally block search crawlers.
Do AI companies actually respect robots.txt?
The major, reputable ones — Anthropic, OpenAI, Google — have publicly committed to honouring robots.txt directives. Smaller or less transparent operators may not. For higher-stakes content, robots.txt alone may not be sufficient protection.
How do I know which AI bots are visiting my site right now?
Check your server access logs and filter by user-agent strings. Tools like Google Search Console, Cloudflare Analytics, or third-party log analysers can help identify unusual crawl traffic. Searching for known bot names (GPTBot, ClaudeBot, CCBot) in your logs is a good starting point.
Should I block all AI crawlers or just some of them?
It depends on your goals. A blanket block is simpler and more protective. A selective approach — allowing bots from tools that cite and link back to sources — might offer some visibility benefit. Review each bot individually before making a final decision.
Conclusion
The question of whether to block or allow AI crawlers like ClaudeBot isn’t going away — if anything, it’s going to get more complicated as more AI systems come online and legal frameworks catch up with the technology.
What’s clear is that site owners now have a genuine choice to make, and doing nothing is itself a choice. Taking thirty minutes to update your robots.txt, review your server logs, and think through what your content is worth will put you in a much stronger position — regardless of which direction you decide to go.
The web is changing. Understanding who’s reading your site, and why, is a basic part of operating thoughtfully in that changing environment.
Want Help Managing Your Website’s Crawler Strategy?
If you’re unsure how to handle AI bots on your site, or you’d like a broader review of your technical SEO and site health, we’re happy to help. Whether you want to talk through your options or get hands-on assistance, reach out to our team at any time.
Email us at moc.ssobebolg@ofni or call +353 1 868 2345 — we’ll be glad to point you in the right direction.
Dublin's ROI-Driven Digital Marketing Agency Home
Related Posts
 Robots.txt Best Practices for SEO in 2026
 Dublin Technical SEO: Configuring Your Robots.txt File
 Robots.txt File Audit & Optimization | Dublin SEO Experts
 WordPress full site editing how to create a child theme block theme
 Globe Boss Digital Marketing Agency Dublin
 Globe Boss Creative Agency Dublin
 Dundrum Local SEO: Rank Beside Irelandʼs Biggest Shopping Centre
 Globe Boss Content Marketing Dublin